Why Technical Specifications Matter More When AI Writes Code in Minutes
By Mr. Oleksandr Nashyvan · CEO ·
A client recently sent us a message that looked like a simple question. It went roughly like this: “How much would a new online store cost? Something like these three sites.” Then came a short list of wishes: the ability to manage the catalog independently, currency selection, filters, and online payment. The old site was outdated, the marketplace storefront was not quite right, and they wanted something better.
Answering that question with a number would have been dishonest. Behind the phrase “like these three sites” sit dozens of decisions that each shift the price in a different direction. How many products? Where does the data come from? Which languages? How are prices structured across markets? What happens to the URLs of existing pages when the new site launches? Who updates the catalog, and how often? None of that is visible in a screenshot.
So our response did not start with a price. It started with a proposal to prepare a technical specification first.
In our first reply to that client, we proposed not just replacing the old site, but building a fast catalog that works for buyers, for search engines, and for AI search: not a black box where every change needs a developer, but a structured project with rules under which some changes can be made with AI. We were transparent that the reply itself was drafted with AI assistance, and said so directly. We were proposing an approach where AI works openly and within limits, so it made sense to show that from the first message.
The Speed Argument Works in Reverse
The most common pushback we hear at this point in a conversation is a version of the same question: if AI writes code in minutes now, why spend time on a document?
The answer is the opposite of what people expect. The faster code gets written, the more expensive a wrong direction becomes. In the past, a misunderstanding in the requirements would surface after a developer had spent a week on the first version. That was painful, but recoverable. Now, an AI agent can build half a system on a flawed foundation in the same amount of time. The speed is real. The cost of a wrong starting point is real too, and it arrives faster.
There is a second reason that is specific to how AI agents work. A human developer can ask a clarifying question mid-task, or draw on memory from a previous conversation. An AI agent needs a written source of truth. When that source does not exist, the agent does not stop. It fills the gap with its own assumptions, some of which will be wrong. GitHub makes the same point in its post on spec-driven development: models are good at continuing patterns, but they do not read minds.
In our practice, the rule “do not invent business logic” only holds when there is a document to reference instead of inventing. That is what the technical specification is, in practical terms. Not a formality before the work begins, but the document that makes the work run correctly.
What a Specification Actually Contains
The word “specification” tends to bring to mind a thick document that sits in a folder and gets ignored. What we build is different. It is a set of agreed outputs that allow development to begin without hidden open questions.
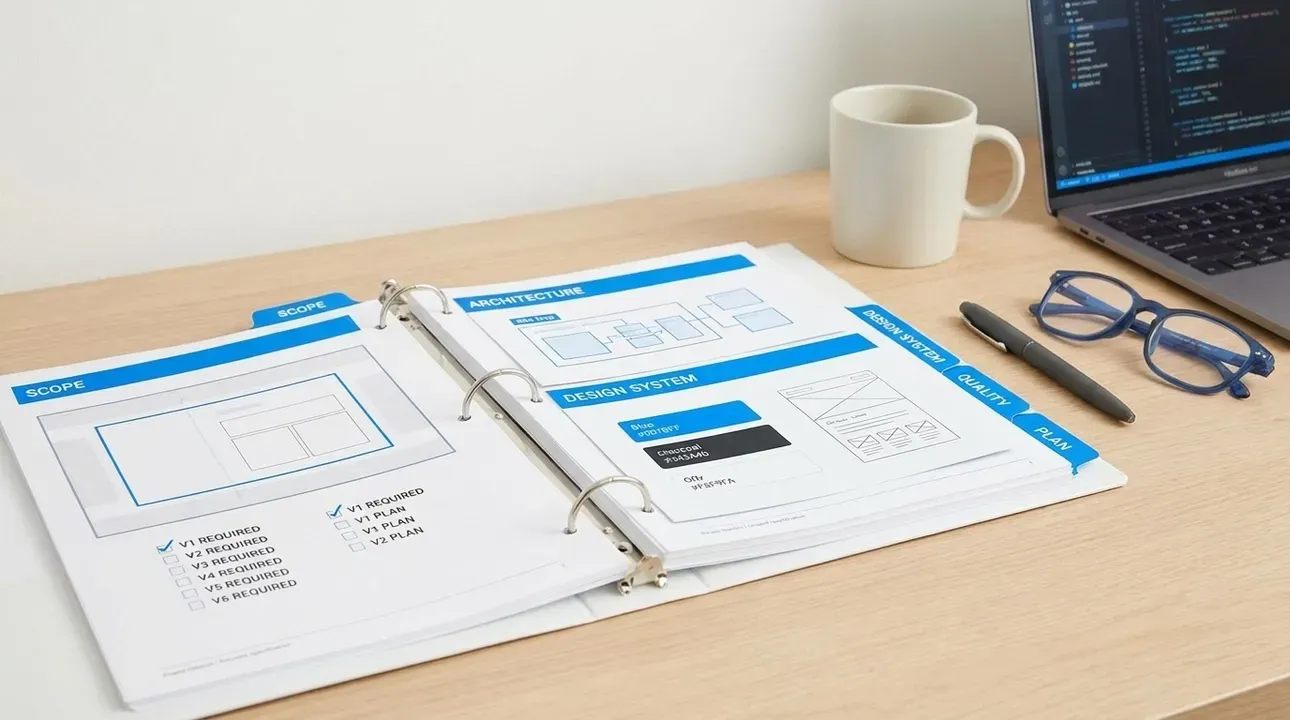
The core of it is project scope: what goes into the required first version, what moves to later stages, and what becomes a separate option with its own estimate.
From there, the structure covers the site and catalog architecture: sections, the category tree, product attributes, and how filters work. The content model defines which data lives where and who owns it. Scenarios describe what a buyer does, what a manager does, and what an administrator does, so edge cases surface before they become bugs. The design section is a resolved design system and page templates, not a phrase like “modern and light.” Quality requirements are written as measurable, verifiable conditions covering speed, accessibility, SEO, and visibility to AI systems, not vague goals.
The plan covers stages, dependencies, risks, and ongoing costs. And there is a register of decisions made, risks identified, and questions still open.
One thing that is not in the document: positions in Google, mentions in ChatGPT, or sales growth. No one can commit to those as acceptance criteria. We write the technical conditions that create the foundation for them, and we write them so they can be checked.
Where AI Actually Fits in the Process
AI is involved in almost every step of preparing a specification. The key word is “involved,” not “in charge.”
Research comes first. Crawling the existing site, analyzing search data, reviewing product export files, and mapping competitor catalogs all happen through scripts written with AI assistance.
Writing follows. Sections of the specification, summaries of client calls, and question lists are drafted by AI from recorded facts. The operative phrase there is “from recorded facts.” The model works from what was captured, not from inference about what the client probably meant.
Verification is where AI catches what people easily overlook. When a project produces dozens of interconnected documents, contradictions accumulate. Requirements in one section can quietly conflict with constraints written in another. AI cross-checks those documents and flags the gaps before they reach development.
The design process is part of this too. We build design systems in HTML with AI assistance and review them in a browser against real data, rather than working from static mockups in a separate tool. What you see is how it actually renders.
What stays with people: the facts, the priorities, and the approvals. The client confirms the things only they know, like which product attributes matter to their buyers, or how their pricing logic actually works across regions. The person responsible for the development process resolves the contested cases and signs off on the final document. AI prepares the ground. People make the decisions.
Why This Matters Before a Single Line of Code
A well-prepared specification does one thing above all else: it removes surprises. Not all of them, but the ones that come from misaligned expectations, which are the most expensive kind.
When a client can read a document and see exactly what will be built, in what order, and what changes the price, they can make real decisions rather than reacting to estimates they did not understand. When the development team has the same document, the work can move in blocks with clear acceptance criteria.
And when development starts, that same document becomes the instruction set for AI agents. They build what was agreed, not what seemed reasonable at the time.
This post opens a new series on how that process works from the inside. We will cover how we establish the process itself before writing a single requirement, why we research independently before asking the client anything, how every conversation becomes a file and every decision becomes a record, how the client-facing document assembles automatically, how we design in HTML without Figma, where human judgment is irreplaceable even with capable AI, how to estimate a project honestly when agents are doing the building, and how a specification turns into work for developers and AI agents.
The series starts where every project starts: before the work, with the question of what the work actually is.